
Last week I closed the Kimi K3 post promising you that I’d do the same exercise of explaining the improvements of the newly released Qwen3.8 and GLM5.3 models in plain English. It turns out that as I was writing this post Qwen and GLM decided to also release their new Flash models (marking that day in the calendar AI independence day), so I guess this is going to become a three post series after all.
One of the things that I really liked about GLM5.3 and Qwen3.6, and that is worth analysing, is that the models don’t introduce any architectural change.
What GLM5.3 is
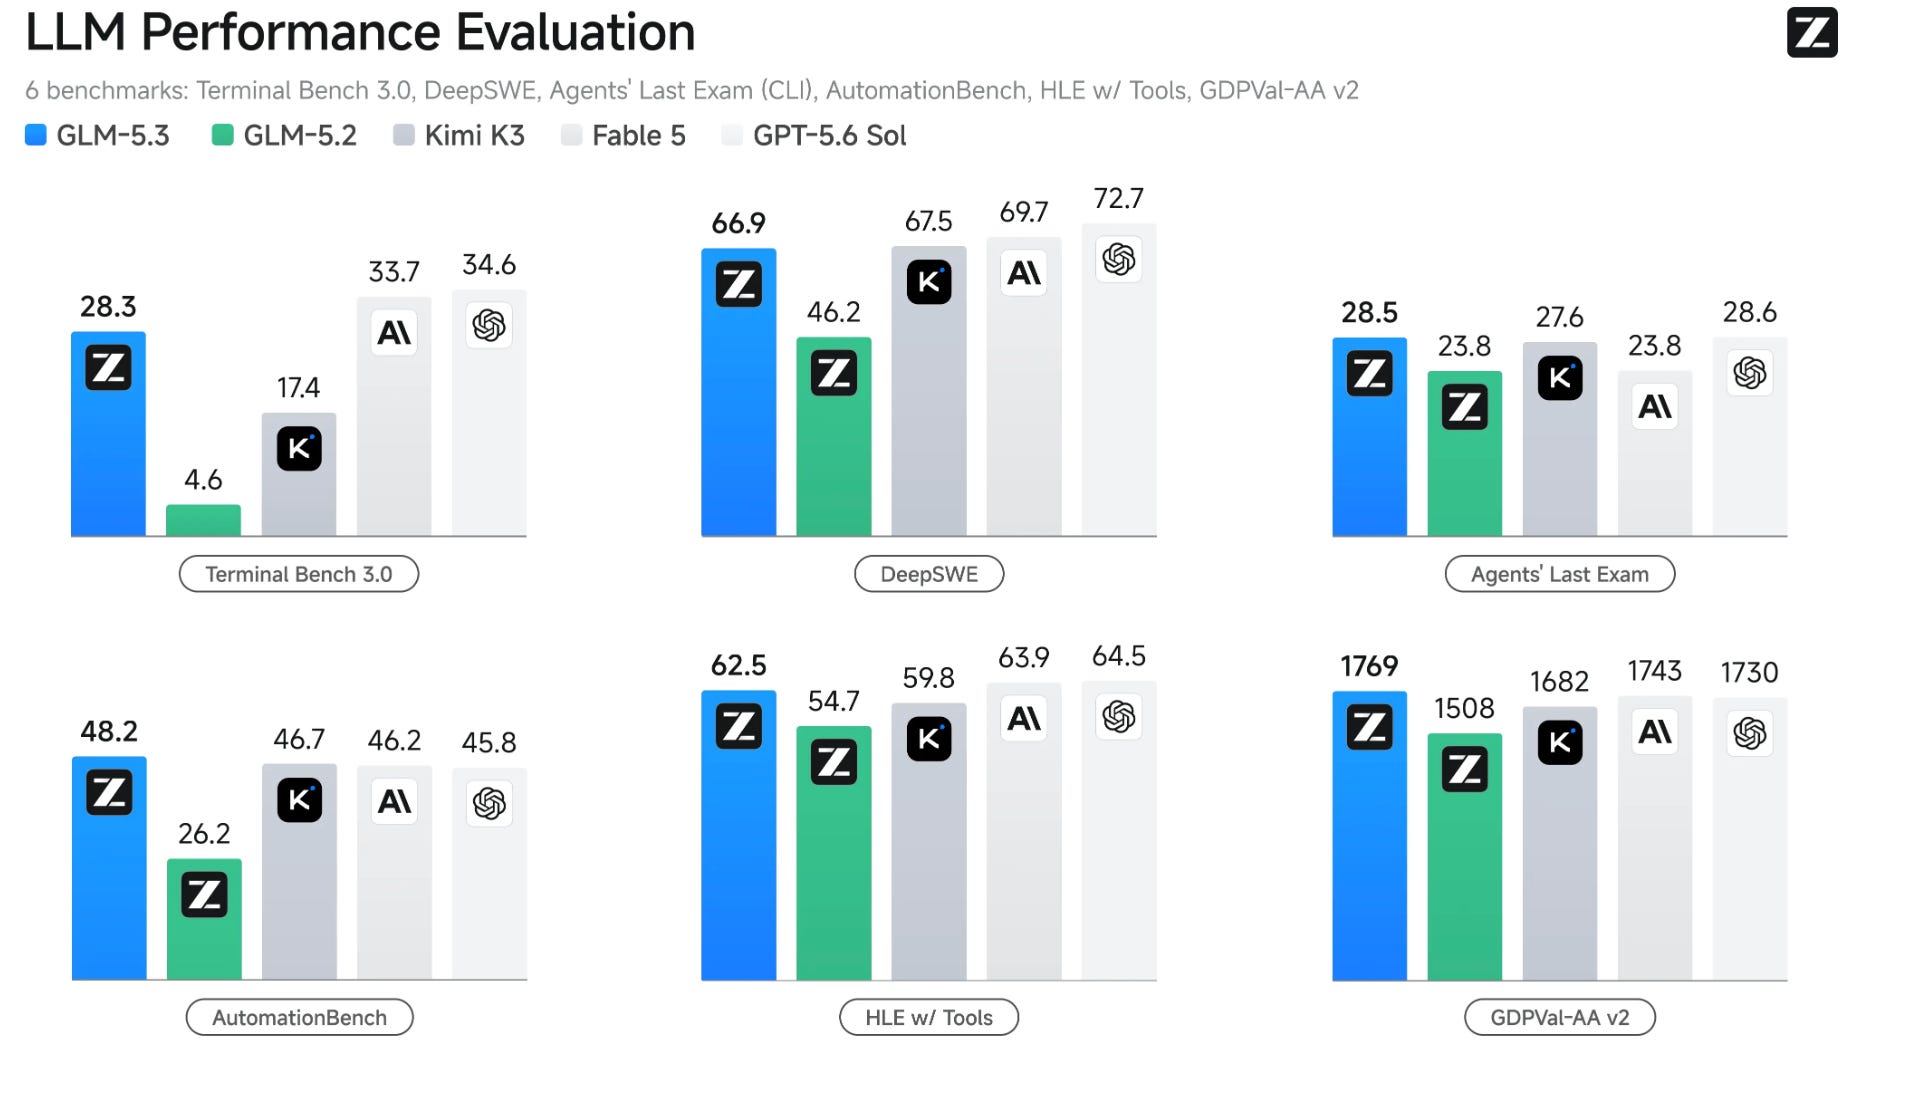
GLM-5.3 shipped on August 14 on the same base as GLM-5.2 (with the same size and number of parameters) but with an additional month of post-training. Z.ai summarises the release as follows: “Scaling post-training is all we did for GLM-5.3.” That was enough, a month of training later, and the same underlying brain made it into the top ranking of CyberGym and GDPval.
Through that month of training, the model managed to get close in the ranking to some of the frontier models, and even beat in some benchmark significantly bigger open models like Kimi K3. But let’s go with my own personal vibe-benchmarking. As many of you know, I also hold a GLM subscription, so I tested it as soon as it got out, and it is good. I already loved GLM5.2, and I honestly wasn’t expecting to feel the bump from 5.2 to 5.3, but I definitely did. I don’t know why, but it feels faster, smarter, and straight to the point (something that I really appreciate from my LLMs, and not only because that way I spend less tokens per task).
Many gossipmongers in the X-sphere are attributing this improvement to distillation, i.e. the model being trained from traces from some of the top frontier models like Fable or GPT-sol, but I feel like distillation in itself can’t explain this bump in performance, and even less when the big labs are being so protective of their own reasoning traces (more on this on some other post).
So then, how can we explain such an improvement only through training? Let’s do a slight detour to explain the different training stages of an LLM, and how we can squeeze every drop of intelligence through additional post-training (depending on the task).
What post-training can do to your model
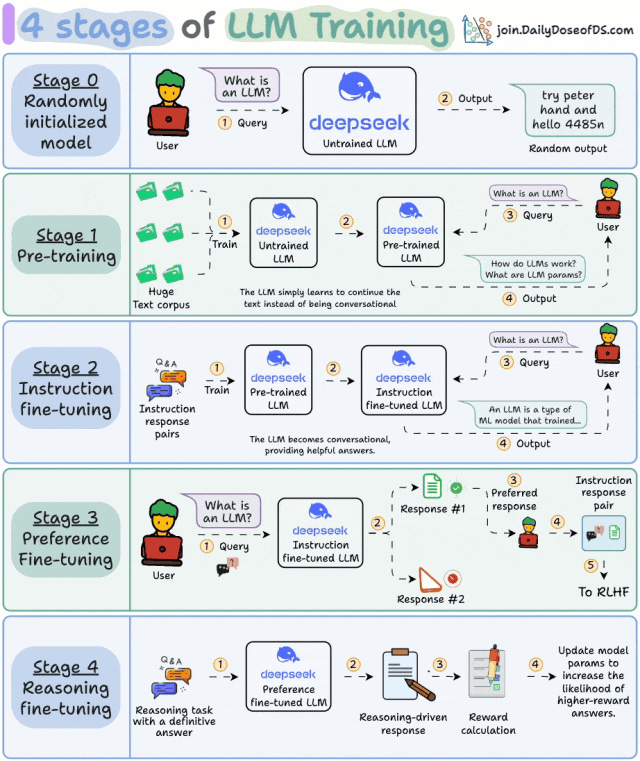
The first stage of training of an LLM is the pre-training. In this phase, the model reads a substantial fraction of the internet (and now some other sources like books and papers packed in different datasets) and learns to predict the next token. What this provides the model is what is called “latent capability”, meaning that the model ends up knowing skills like Python, C memory semantics, or how to write proper English just by reading a humongous amount of text, and being able to predict accurately what would come next. If you ask a pre-trained model to produce a poem or a plausible-looking bug report from a Stack Overflow thread, it will probably do a good job, because all of that exists in its training corpus.
This the most expensive stage in the training of an LLM, and it’s one of the stages that GLM5.3 didn’t touch at all (same architecture, no pretraining).
Then comes mid-training, which is a stage that not many people consider because it is an intermediate stage where a similar process as the one for pre-training is done over a base LLM model (from pre-training) with curated data, long-context extensions, more codes, domain-specific datasets, etc. just to improve a little bit those “latent capabilities” from the base model in specific domains. GLM5.3 didn’t touch this stage either.
And then comes post-training, This is where the base model gets turned into something that has a specific behaviour (and in many cases personality), and is able to perform specific tasks (like the agentic ones that we keep asking them to do). The post-training phase in itself has three different stages.
Supervised fine-tuning, where you show the model demonstrations of good behavior and train it to imitate. This is where instruction-following, response format, and refusal behavior come from. The signal is grounded in someone else’s output. Which means that the model learns to copy perfectly specific behaviour. This is the part of post-training that can be improved through distillation, because you can take a big corpus of outputs and reasoning traces from more intelligent models in specific tasks, and use it as the input for the supervised fine-tuning.
Preference optimization (RLHF, DPO, and friends), is what achieved the GPT-4 leap (that it feels like it was decades ago). In this stage humans rank pairs of responses, fit a reward model to those rankings, and then optimize the policy against that reward model. The signal is grounded in a learned proxy for human taste. Also largely copyable, because taste is legible in the output, and potentially something where a good corpus of training data could be created through distillation.
And finally, reinforcement learning with verifiable rewards. The prettiest girl in town from last year. The model is dropped in an environment, takes hundreds of actions, and gets a reward computed by running something. The tests pass or they don’t. The crash reproduces or it doesn’t. The signal is grounded in execution. For RLVR, there needs to be a clear objective goal and scoped environment that LLM uses to train and understand through a reward loop how good it is doing in a specific task. One of these environments is what led to the Open AI model attack to Hugging Face (see report). But once again, let’s leave that topic for some other post.
This last stage is what explains the improvements in GLM5.3. For GLM5.3, Z.ai decided to improve the environments that they were using in this post-training stage. Most environments built so far look like coding challenges: self-contained puzzles with a checker, textbook problems with the answers at the back. GLM-5.3’s environments, in z.ai’s words, “look less like coding exercises and more like real units of expert work”. Some represent several days of work for an experienced engineer. The blog’s example is an ML infrastructure task: the model gets the same working environment an engineer would, compute clusters, storage, internal documentation, codebases, and experiment results. It has to diagnose bottlenecks across the training stack, implement optimisations, run its own experiments, and deliver a measured end-to-end speedup without breaking correctness.
I think this sentence from the report explains it all: “as agent capability improves, much of the difficulty in scaling post-training moves from the model to the environment.” So the model stopped being the bottleneck and now the challenge is in training it to perform the specific task.
One can’t hand-build thousands of multi-day expert tasks to train the model, so to work around the bottleneck they built an environment factory. Research agents collect task patterns from real work and turn them into runnable long-horizon environments with hidden state and multi-step dependencies. A judge agent has to actually solve each task before it counts. An exam nobody can pass never gets set. Then a solver runs and probes each environment for shortcuts, ways to score without doing the work, and get them closed. The result is a training curriculum that writes and grades itself, with humans reviewing the edges.
I described my “Spec-Test-Lint” coding flow in January, and its core was: the more complete the spec, and the closer the tests to the spec, the more autonomously the agent can work. What I was essentially doing was hand-building tiny gyms for my coding agent with a clear and objective feedback loop for a specific task. To some extent, Z.ai did the same but at scale and for model training for RL (this is an analogy that may not match 1:1, but I was trying to stress once again the importance of having objective feedback loops for agents).
As part of all this, Z.ai mixed vulnerability-discovery data and environments into training. They expected the model to get better at finding and reasoning about flaws. Then, in their words, “cyber capability developed faster than we expected”: the model “began to reason across multiple stages of exploitation, forming coherent plans for complete exploitation chains”.
So they took it to the real world to check. Working with security teams and running against real codebases, after expert review and deduplication, the model identified 2,436 vulnerabilities across 269 open-source projects, 1,097 of them medium-to-high severity. The oldest flaw dates to 1981. The average vulnerability had been sitting there for 26.6 years before anyone noticed. Z.ai is running the disclosure through a public ledger (cvd.z.ai): 53 issues disclosed so far, 2,383 still under embargo.
So by trying to improve their reasoning they taught the model how to hack.
From GLM5.3 to Qwen3.8
Qwen3.8-27B also shipped on August 14, the same day as GLM5.3. The reason why I was so excited with the release of this model is because, unlike GLM5.3, you can run Qwen3.8-27B at home with hardware that costs you less than 10K$, like a Mac with enough unified memory, a DGX Spark, or a RTX3090. GLM5.3 was exciting because it upgraded one of my favourite open models, but Qwen3.8-27B gives me an upgrade of my home intelligence (which translates in infinite token quotas).
Before we jump into the changes under the hood, what was crazy to me, is how in their announcement they decided to compare directly with Opus4.6-Max (legends). So essentially, we are getting a previous generation Opus-like model that runs in home hardware (I still need some time to continue testing it to determine how good it feels compared to Opus 4.6, but just the promise of this, even if it “benchmaxxed”, is an achievement).
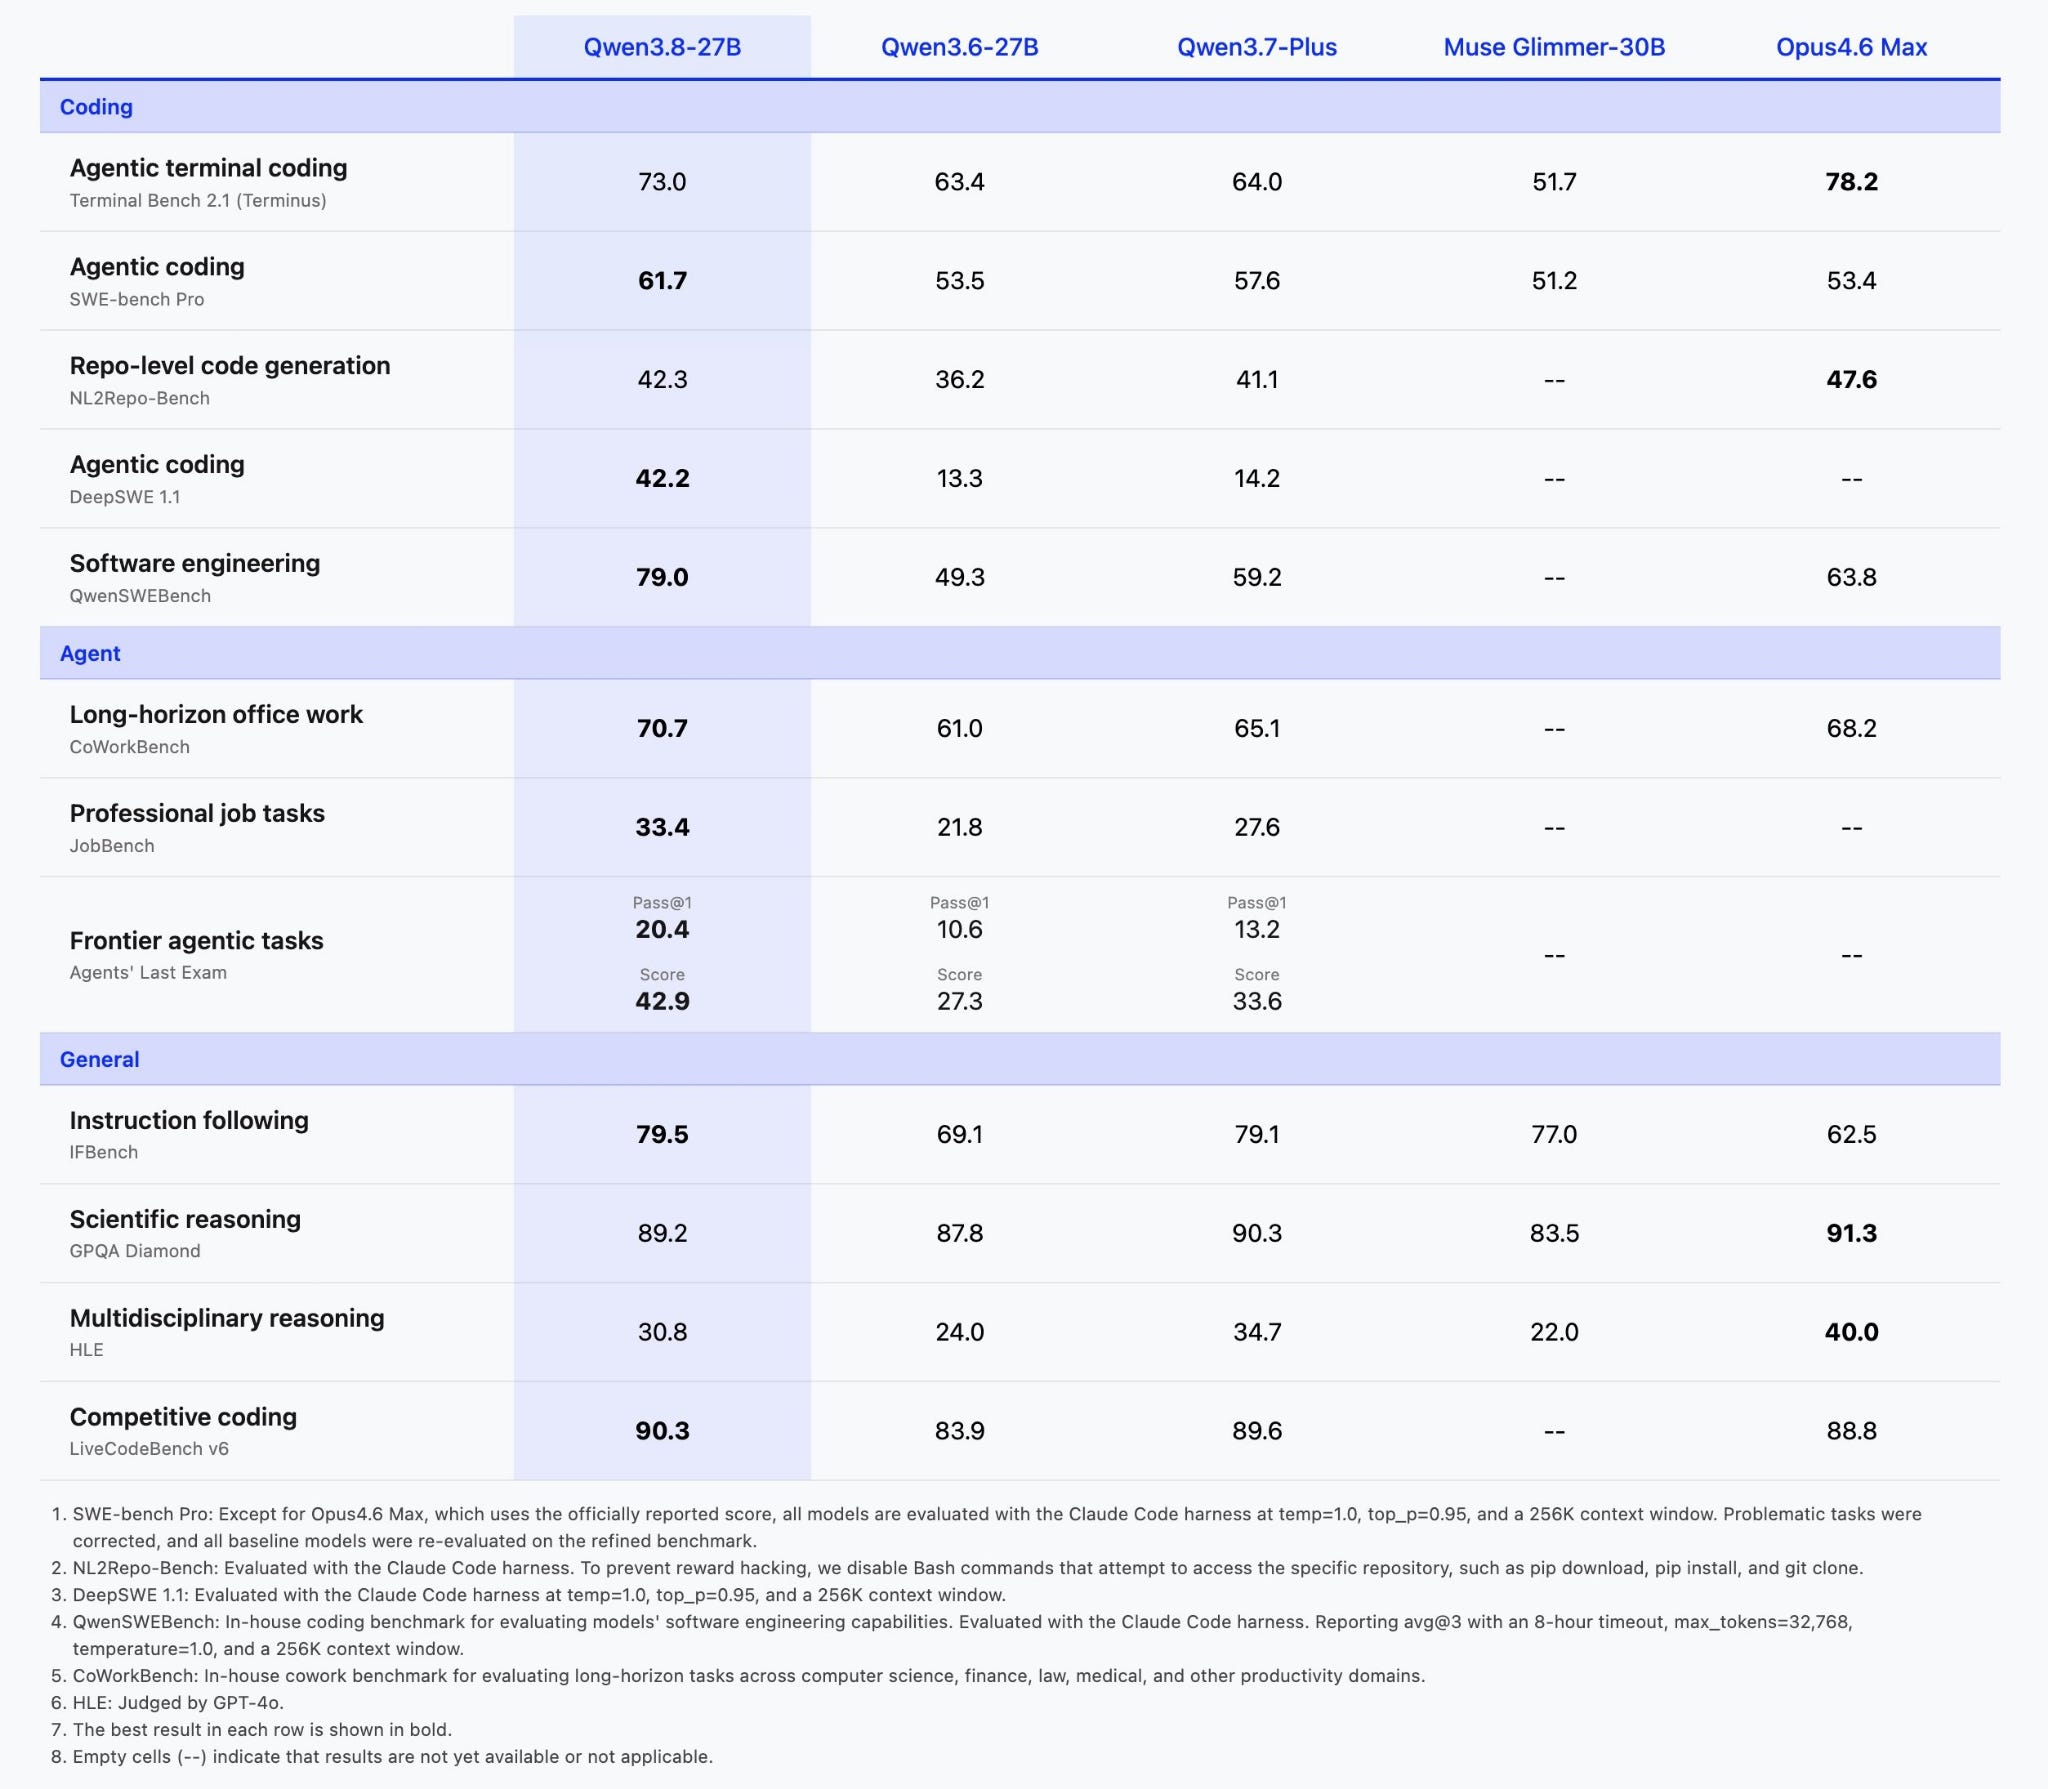
If you look at Qwen3.8 model card you’ll see that the model is “built on the architectural foundation of Qwen3.5” (actually, if you look at the model_type you’ll see that it still says it is qwen3_5). The layer count, hidden dimension, FFN width, head layout, and native context are all essentially unchanged from 3.6-27B. The main difference in the minor version bump between GLM-5.3 and Qwen3.8-27B is that Qwen did retrain. B. The hybrid attention layout is inherited, not new: 64 layers arranged as 16 repeats of three Gated DeltaNet (linear attention) blocks followed by one Gated Attention (full attention) block, with multi-token prediction trained across multiple steps. Nice design, but it’s a 3.5 design (we’ll leave explaining each of these layers to some other post).
The model card lists the training stage as “Pre-training & Post-training”. While Z.ai explicitly froze the base and only pre-trained. So what we can learn from these two releases is that while war knowledge scales with the number of parameters, long-horizon reliability is a post-training property, and a small model with good post-training can beat bigger models at doing certain tasks (even if they know less about the world).
There doesn’t seem to be any environment-factory writeup, or RL methodology nor corpus disclosure in Qwen’s training. Reading the model card and the report of Qwen3.8-Max, there were a few things that stood out to me.
The first is that preserve_thinking is on by default, retaining the thinking blocks from every historical message rather than only the last turn (unlike in Qwen3.6). What this means is that the RL rollouts kept the model’s own reasoning in the window as the episode ran, so the model learned to treat its past thinking as working memory instead of regenerating a fresh rationale every turn. Qwen gives three reasons for this: decision consistency across long runs, less redundant re-reasoning, better KV cache utilisation. Thinking blocks that stay put in the prefix stay cached. Thinking blocks you throw away and rebuild every turn are the reason agent loops get expensive.
The second is reasoning_effort, with xhigh, medium, and low, and xhigh as the default. Three budgets means they trained the model to actually behave differently at three budgets, rather than shipping one policy and hoping a system prompt talks it into brevity. And unlike GLM-5.3, thinking can still be switched off entirely.
The third is the “Downstream Compatibility: broader support for popular harnesses”, which is listed as a headline feature, and every coding benchmark in the card was run through the Claude Code harness. This is the same lesson that Z.ai learnt in GLM5.3: if you want a model to work inside a real agent loop, you post-train it inside a real agent loop, with real tool-call formats and real error messages coming back at it. Which is also why it drops into OpenCode or whatever you already use without a wrapper and it works just fine (seeing how we currently use these models, and if you love pi as much as me, every model should be doing this).
What these releases tell us?
Z.ai froze the base and spent a month building environments. Alibaba shrank the model by a large factor and improved their post-training pipeline to squeeze more intelligence in less space. It is crazy what open models have achieved in just a few months, we can now have previous generation Opus-level intelligence at home, and a model that with some REAPing you could get running at home with a bit of hardware investment. And I still haven’t started talking about GLM5.3-Flash and Qwen3.7-Flash (that marked for me AI independence day, and that I’ll leave for next week’s post).
Back in July I argued that the future is narrow, that REAP-style expert pruning lets you cut away everything a model knows that you’ll never ask about, and keep the part you need on hardware you own. In that post I argued that we can compress an existing model removing all the experts that were irrelevant for the task at hand. This post is the other half of the same trade (and why I am so excited about these models that can run at home). Base models embed a lot of raw knowledge inside them, and this knowledge scales with the number of parameters, but we can use that base model and prune it in order to steer it through post-training to be good at specific tasks, even with a reduction of their core parameters. We model the raw knowledge to become performant in the tasks we are interested in (model is becoming a loaded word).
I don’t know about you, but with how things are evolving, I am seeing closer and closer the day where we can run these models “cheaply” at home (or in the cloud, for those with a bigger risk appetite), and we can have plug and play AI. We are getting closer to “the solar panel moment’, and China once again is the catalyst for it (note to self: I should also write about my ideas around this).
See you next week to analyse AI independence day. Until next week!
That’s good writing, mate.