

I gave a talk earlier this year at CONVEX, in Madrid, in an actual cinema. The talk was my attempt to put everything I’ve been circling in this newsletter for the past few months into a single forty-minute argument about local AI, why the company everyone wrote off might win the infrastructure war, and why I think we should all be quietly building our own way out.
This is me rounding off the local-AI series (and “the writing season”) with it. No new arguments this week. This talk was the perfect excuse to try and put all the posts I’ve been exploring on the topic in the same place..
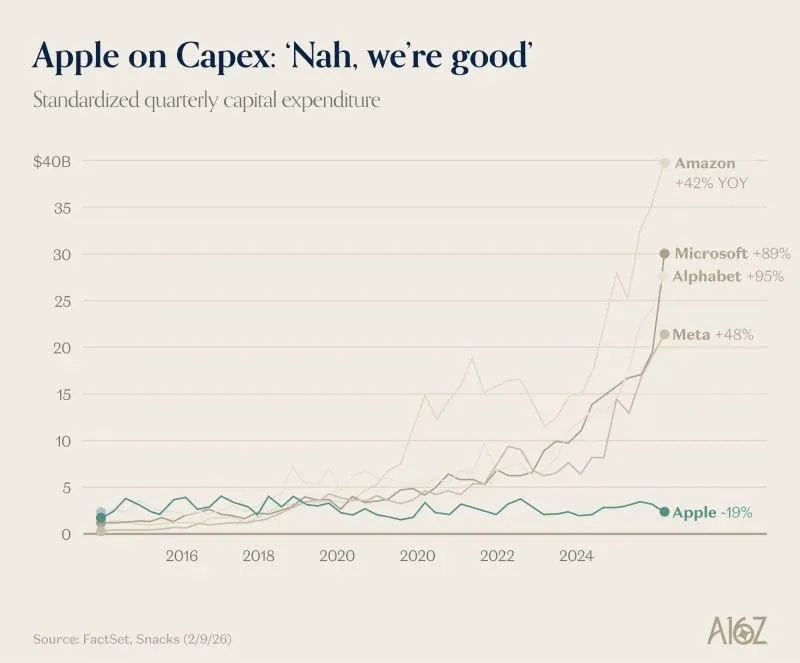
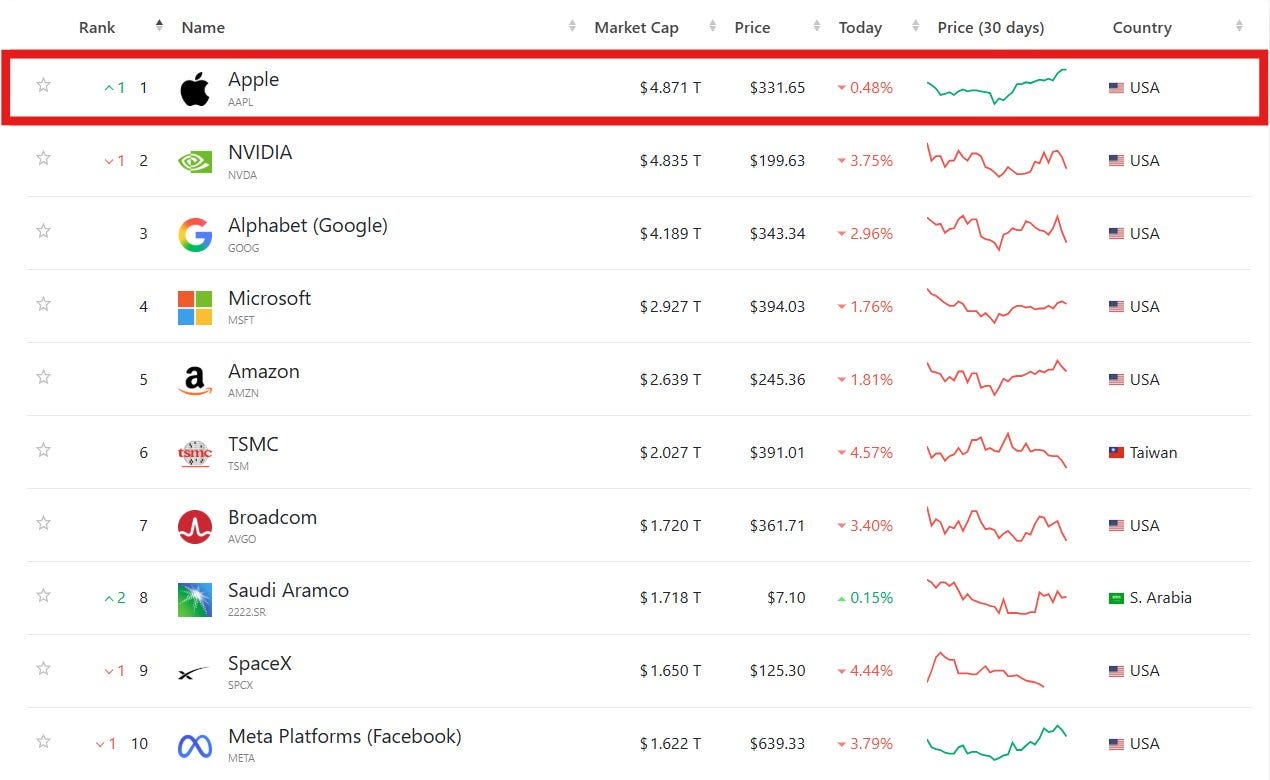
That talk happened in mid-June, so I could have posted at any point since then, but this week made the perfect timing for it. On Friday Apple briefly overtook Nvidia as the most valuable company in the world (again) for a few hours. Apple was the most valuable company in the world already a while ago, but with the advent of AI, many were seeing a loss in their lack of a frontier model. But think about who Apple passed to get there. Nvidia sells the shovels. And right behind them, Amazon, Microsoft, Alphabet and Meta are about to spend a combined $725 billion on AI infrastructure this year, up 77% on last year: roughly $200bn from Amazon, $190bn from Microsoft, $185bn from Alphabet, $125bn or more from Meta. Apple is spending a rounding error next to any of them, and for one afternoon it was worth more than all of them.
This same week, Moonshot shipped Kimi K3, a 2.8-trillion-parameter open-weight model that can be considered Fable-level, with its full weights out under an MIT-ish licence within the week (I can’t wait to get my hands into one of those GGUF, even if I can’t run it). So on the same day open-source got their first frontier-level model , the market rewarded the company that decided to sit out of the model race. As I mentioned a few times in this newsletter, intelligence is clearly commoditising.
My CONVEX talk
I received the invitation to talk at CONVEX in May, and since then I think I have had to update the slides at least five times. Things were changing every week, and every version went stale the day I finished it. I’ve spent two years telling myself not to write about anything trendy for exactly this reason, and then went and built a whole talk on the trendiest thing there is (never trust your own advice). My thinking has moved on since (so apologies in advance for potential inconsistencies), but the shape of it still holds better than any single post of mine does. If you’ve only got the patience for one thing from me this year, this is probably the one.
“Model Race Hangover: Why the AI Loser May Win the Infrastructure War”. CONVEX 26, Madrid. Roughly forty minutes, plus a genuinely good Q&A at the end that I’d not skip.
The posts this talk built on
Some people prefer to consume videos and audios rather than written content, and the opposite side also exists (I personally lean more towards the latter). So for those that like to read and haven’t been around for a while, here are a few of the posts that laud out the arguments shared in the post..
The spine of the whole thing is that intelligence has become a commodity, and context is the moat. Once you believe that, the company everyone called the AI loser stops looking like a loser: Apple didn’t join the model race and quietly ended up holding the unified-memory hardware and the personal context that actually matters. This may be what the market was starting to see on Friday when Apple became the most valuable company in the world again. And the layer above the raw models, the software you’d pay for, gets rebuilt too, which is the case I made for agents replacing SaaS.
The next big argument I’ve been sharing throughout these past months. I don’t think we’re in an AI bubble. I think we’re in an AI trap. The models are useful and they’re being sold to us below cost, which is a great deal right up until the day it isn’t, and the people who lose access first are the token-poor. And even with all that money going in, I still think an AI winter is coming, not a technical one this time but an adoption one, because we’ve genuinely useful technology and, coding aside, almost nobody has worked out how to use it beyond bolting a chatbot into a textbox. The trap has a bit of bubble-vibes in any case :)
The way out of the trap is to own your own stack, and this is where most of the practical talk goes. If you want to run models yourself, the number that decides everything is memory bandwidth, not the GPU everyone tells you to buy (they are definitely required, but may not be the critical one. I just realised than neither in the talk nor in any of the posts I talk about the difference between token throughput and prefill numbers, I’ll need to spend some time on this in the future). Then it’s the models and the engine that runs them: mixture-of-experts versus dense, llama.cpp as the ffmpeg of inference, all the tricks that turn a spec sheet into actual tokens per second. And you can get a long way with a small (another one of the big ideas I’ve been having and that I’ll need to develop and share this next season), even nerfed model if you treat it as a reasoning engine you feed fresh context rather than a memory you interrogate.
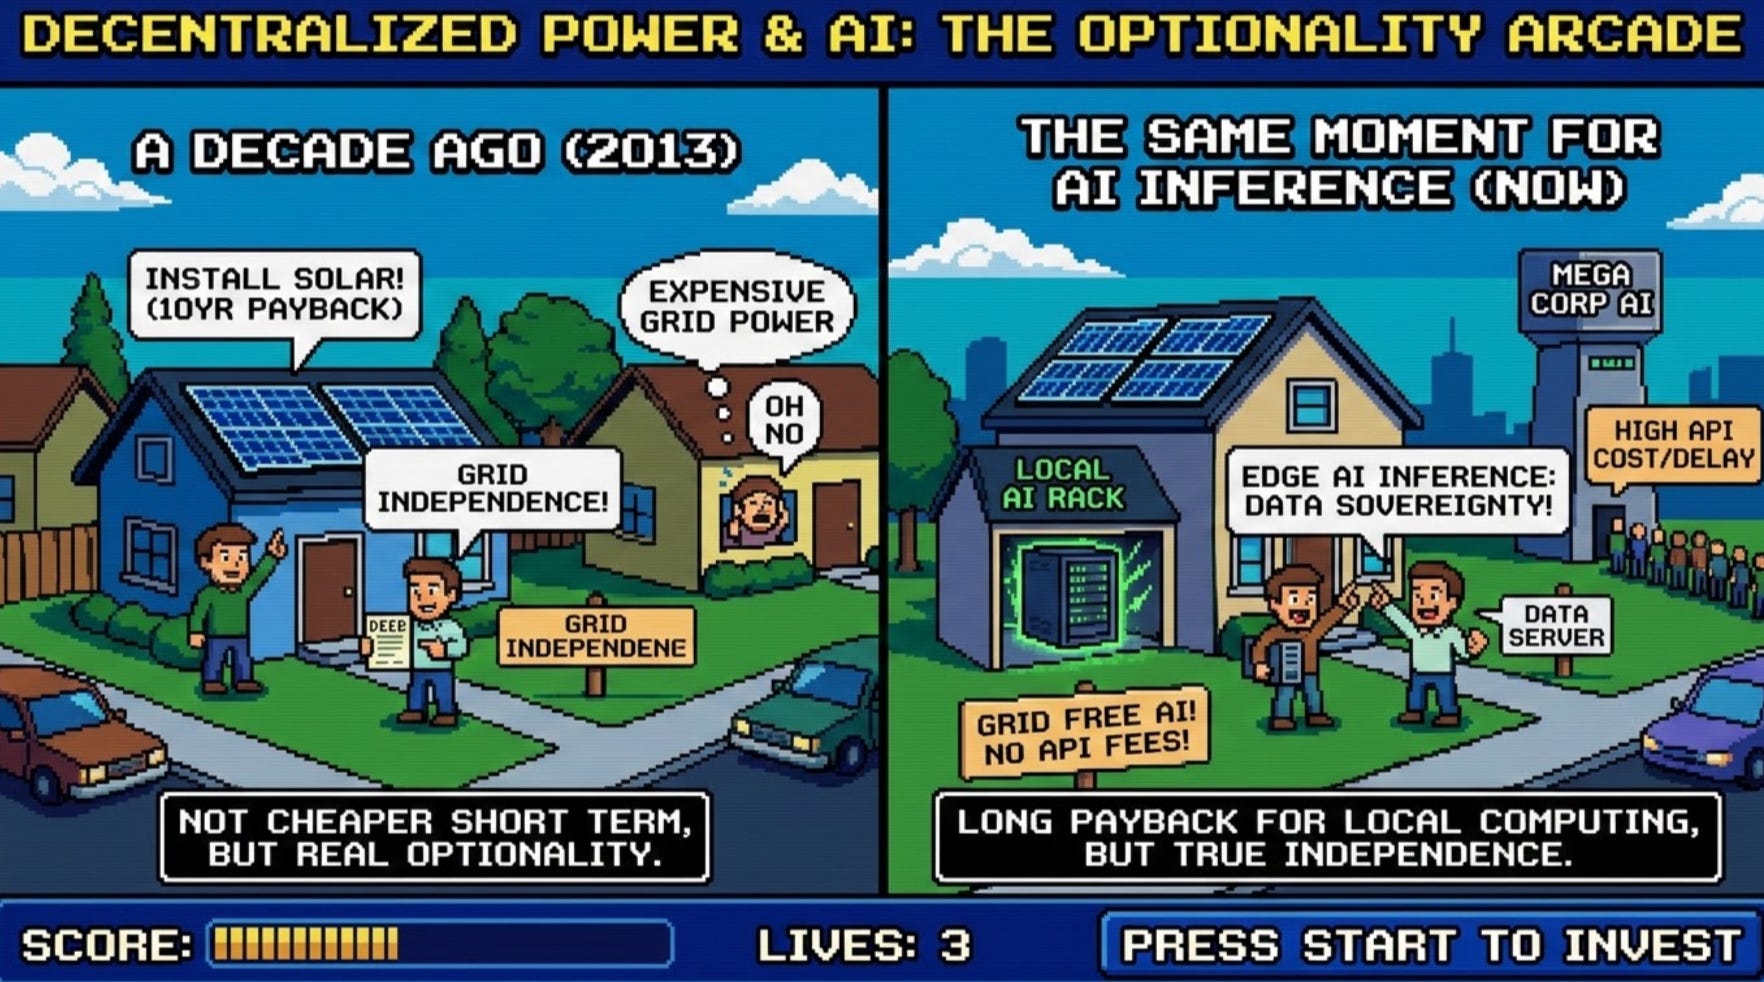
Put all of that together and you get the thing I keep coming back to: a plug-and-play box for AI. The solar panel for intelligence. Something you buy once, that runs locally, that doesn’t leave you renting a lab’s API forever. I still don’t have it built. I said as much last week. But I’m more convinced than I was on that stage that it’s where this goes.
Where I’ve moved since
The talk is a snapshot, and the newsletter has run ahead of it in a few places. The biggest one is that I’ve gone from hand-waving about “small models for your use case” to the actual mechanism: you can surgically cut a frontier model down to the experts your one job needs and lose almost nothing. The China open-weight story has hardened since I spoke, too, which makes owning a good copy feel less like a hobby and more like insurance. And I’ve become convinced the box is two problems, not one: the model you run, and the engine that runs it. The talk only really covers the first. The posts have started on the second.
What’s next?
As mentioned above, I know some people prefer to watch and listen rather than read. I’ve wondered for a while whether some of you would get more out of hearing me than reading me. A narrated piece, or a talk, or an interview, once a month instead of one of the Sunday posts. I’ve tinkered with the idea for ages and never found the motivation to do it properly, mostly because I genuinely don’t know if it fits what you come here for. This post is a cheap way to find out.
So tell me. If you watched the talk and would take a monthly version of that over a written post, say so. Reply, leave a comment, react, whatever’s the least effort for you. If enough of you want it, I’ll try it and we’ll see if it’s any good. If not, I’ll happily keep writing on Sundays and we will never speak of it again.
And why all those mentions of the “end of the season”? Well, I still haven’t decided on it, but I am considering taking the month of August off of writing in this newsletter to collect some ideas for my backlog. I already have a fresh one that I may not want to keep left in the bedroom until September, so you may hear from me earlier than planned.
Until September or next week, we’ll see!