
Back to our regular schedule, welcome back to a new season of “Beyond the Code”.
These past few weeks that I haven’t been around, we’ve seen a good number of new open model releases. Open models have been my daily driver for months. That has meant accepting a gap in the capabilities I had compared to proprietary models: for most of what I do they’re fine, and for the harder things that were frustrating me to the point of throwing the towel, I kept a cheap Claude subscription that I could fallback to (I want to think that this has helped improve my model taste).
But a few weeks ago everything changed, Kimi K3 is the first release where I stopped using Claude all along. I saw myself using exclusively a single open model for my day-to-day (the closer I had been to this was GLM5.2, which was already covering almost all of my needs without having to fallback to a proprietary model, but there were still things were Opus came quite handy).
This is a bigger deal to me than any benchmark. I’ve been writing about becoming AI-independent for a while, and this is the first time the independent option (with the permission of GLM5.2) gives me an open model that I could marry to. I know that running Kimi K3 locally is unrealistic (I would have a better chance doing so with GLM5.2), but still… the fact that these are open models means that I can finally switch LLM providers without worrying about losing access to the models I love, letting the free market push the prices to a floor in the process.
Apart from no vendor lock-in, the next thing that I like the most about open-models is that you can inspect their architecture in order to understand the techniques that have made the new generations improve their capabilities.
When I opened Sebastian’s usual architecture diagram of K3, I hit a soup of acronyms: KDA. AttnRes. NoPE. Stable LatentMoE. Gated MLA. Every model release comes with new ideas on how to improve them, and I felt it would be great if for each model, these innovations were explained in a way that everyone could understand what changed.
I’ve rewatched Robert Nishihara explain LLM inference in about six minutes so many times in the past year (I keep seeing it being shared). That video is a masterpiece, without a single equation, you come out of it understanding why serving these models is hard in a way that three years of reading papers may not give you. I love it when someone does that. Being able to follow an industry properly without being an expert in it is a gift, and it is mostly given to you by people who bothered to explain things well (because they deeply understand what they are talking about, and they can communicate the ideas clearly, the Feynman way).
So this week I wanted to do that same exercise with Kimi K3, explaining what actually changed in this model to make it so good in plain (non-native) English.
What Kimi K3 is
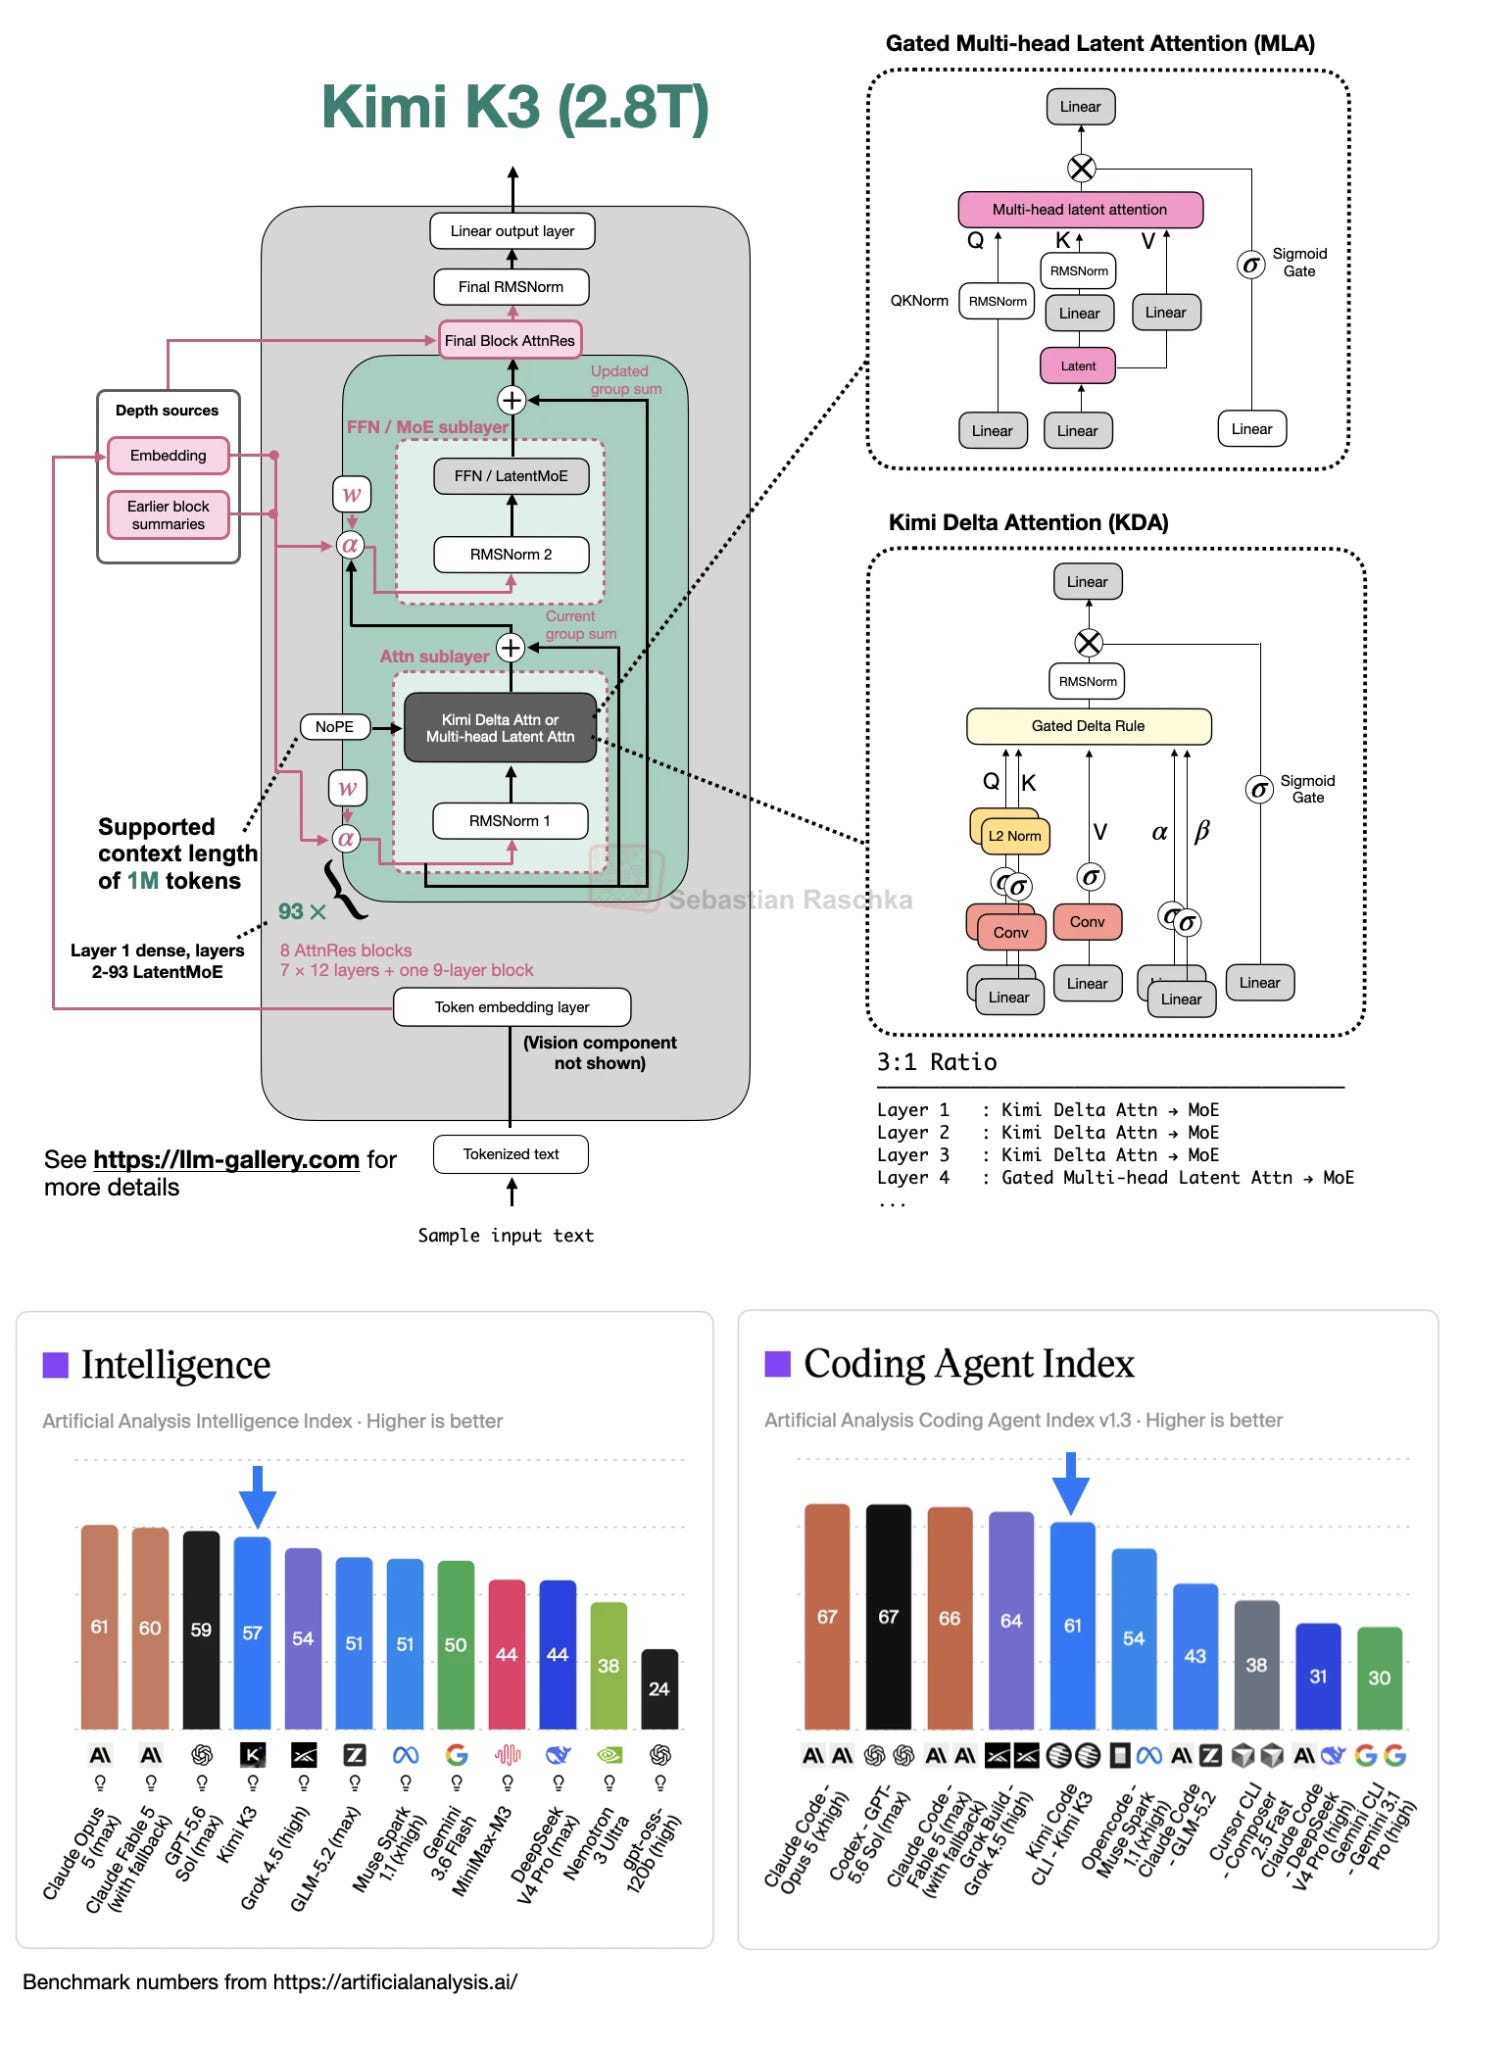
K3 is a Mixture of Experts (MoE, if you’ve followed my newsletter enough, you already know this acronym because I’ve written about MoE twice already) 2.8 trillion parameters model, of which 104 billion fire for any given token. It has 896 experts, 16 active at a time, with a one-million-token context window. It is open weight, and has native vision capabilities.
The parameter count in itself tells us nothing. The important number for this release is the second one: K3 has 104 billion active parameters, up from 32.6 billion in K2. The model got a lot bigger in the number of parameters, and in the number of them that are activated in every pass.
Most of what follows comes from Sebastian Raschka’s architecture notes and the technical report, which is unusually readable for a report of this kind if you skip the equations. Raschka’s first observation is the key to understanding this model: K3 is not a new invention. It is Kimi Linear, a 48B model they released last year with linear attention, scaled up to 2.8T. They took that architecture and scaled it up for production.
The three changes introduced by K3
High-level, three things changed in K3 over K2. A transformer has two directions it has to move information in. Along the sequence, which is the text: every new word needs access to the words before it. And along the depth, which is the stack of layers: every layer needs access to what earlier layers computed.
All the work to make transformers better has been focused lately along the sequence. This is the part that involves the attention mechanism. Each position looks back at all previous positions and chooses what’s relevant, weighting some words heavily and ignoring others. That choosing piece is the whole trick that made transformers better than previous architectures like LSTMs.
Along the depth, transformers have always been a. bit dumber (researchers have paid less attention <unintended pun> to that part). Every layer dumps its output into one shared running total, the residual stream, and every later layer reads that same total. No choosing. Everything gets added into one pile and later layers get whatever the pile currently looks like.
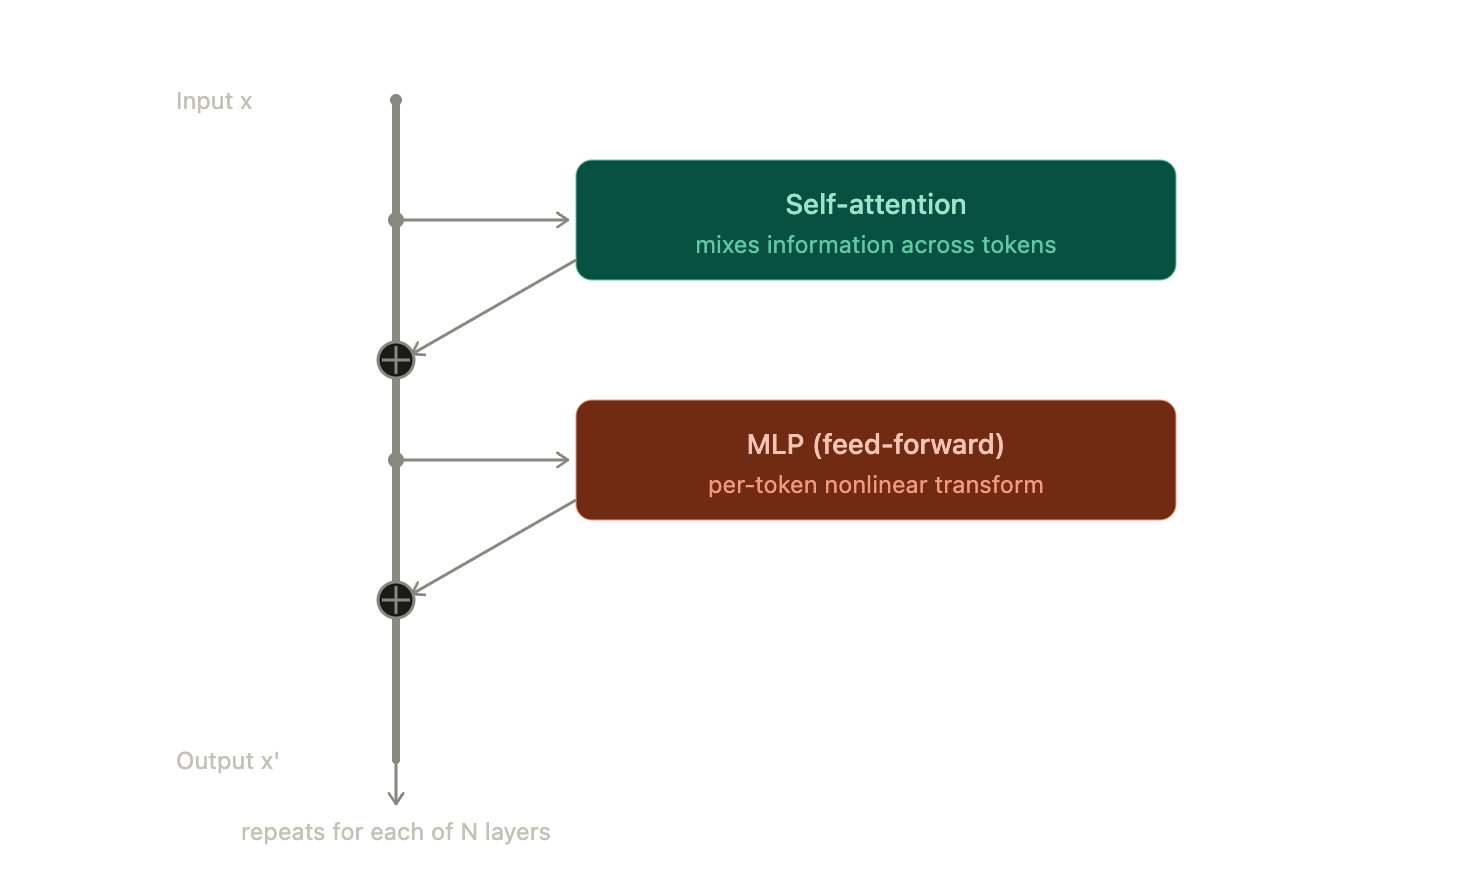
The report describes perfectly what happens here: standard residual connections “compress all prior information into a single state over depth, a bottleneck reminiscent of RNNs over time“. That comparison is doing a lot of work. RNNs were the thing attention replaced, because squeezing a whole sequence through one running state loses too much. This the part in the depth direction mentioned above that until now no one was paying attention to.
All three of K3’s changes are about being more selective, in one direction or the other. Two make the sequence direction cheaper. One finally fixes the depth direction.
I could have stopped the post here (and I highly recommend uninterested readers to stop here), but this is too high-level, and I think these mechanisms deserve a more in-depth explanation.
KDA: a notebook instead of a transcript
An expensive part in a transformer is that generating each new token means looking back over every token before it. Write a ten-thousandth word of a conversation and the model needs to consult the previous 9,999. That’s the KV cache I wrote about last March, and it grows with every word.
The alternative is to keep a summary instead of a transcript. Rather than storing everything and re-reading it, you can hold a fixed-size state and update it as each new word arrives. Fixed size means the cost stops growing. This is roughly what RNNs did, and it’s why they were cheap and why they were worse.
The cost of a notebook is that you have to decide what to write down. In a transcript there is no information loss, while when you summarise something in a notebook, there is some information loss, and forgetting the wrong thing is precisely how these models fail.
Kimi Delta Attention is a better decision procedure about what to forget. The technical version is channel-wise decay applied before a delta-rule update. The plain version: the summary isn’t one blob with a single forget-everything-a-bit knob. It’s split into many channels, each with its own retention setting between “keep this indefinitely” and “let this fade fast”. The model learns which is which in training. Names and instructions can persist while the phrasing of a sentence three paragraphs back decays away.
They use three KDA layers, then one full-attention layer, repeated all the way up the stack. A 3:1 ratio, straight from Kimi Linear. Three layers work from the notebook, then one goes back and reads the actual transcript. There’s a small detail in the report I liked: the very last layer of the model is always a full-attention one, so whatever the model does last, it does with the real thing in front of it.
The payoff is up to 6.3x faster decoding at million-token contexts, and up to 75% less KV cache in the Kimi Linear results. Which is a lot of engineering for something you could summarise as: take notes, but check the source occasionally.
NoPE: throwing away the page numbers
Transformers have a strange problem. Attention looks at all previous words at once, and has no inherent sense of their order. “The dog bit the man” and “the man bit the dog” contain identical words. Something has to encode position.
The standard answer for years has been RoPE (Rotary Position Embedding), which stamps positional information onto every query and key. It works. It also has a well-known annoyance: it’s tuned for the context length you trained on, so stretching a model to longer contexts means rescaling or interpolating those frequencies, which is fiddly and tends to degrade quality at the edges.
K3 has no positional encoding at all. Not in the global attention layers, not anywhere. As far as I can tell (from my limited research and knowledge) it’s the first frontier-scale model to go fully NoPE.
The KDA layers process tokens in order, updating their state one token at a time, which means position is already baked into what they produce. Something that arrived recently has decayed less than something from ten thousand tokens ago. The report calls the KDA layers “position-sensitive and recency-aware”, and that’s the whole answer: by the time a full-attention layer sees anything, it’s looking at representations that already know where they came from. Telling them again is redundant. This is one of the advantages of storing the transcript (that is able to persist order) over a summary.
With no positional encoding to rescale, the model “extrapolates directly to 1M-token contexts without any positional-encoding modification”. The million-token window isn’t a stretched 128K window. There was nothing to stretch.
I honestly don’t fully understand why this holds up as well as it does (if you do, please leave a comment so I can update the post accordingly). Three layers out of every four carrying implicit position, with the fourth flying blind, sounds like it should degrade somewhere, and the report doesn’t really explain why it doesn’t. Nobody removed a component here, they removed a component and got a longer context for free, and I’d like to read the paper that explains that properly.
Attention residuals
The two changes above make an existing thing cheaper, but K3 introduces one more change that allows it to generate tokens faster.
Let’s come back to the residual stream: every layer adds its output to one shared pile, and every later layer reads the pile. Layer 40 wants something specific that layer 12 worked out, and there is no mechanism for asking. It gets the sum.
Attention residuals give layers a way to ask. Each layer gets a small learned probe, a “pseudo-query”, which it uses to look back over the outputs of the layers beneath it and weight them by relevance. Instead of reading the pile, a layer chooses what to pull from and how much.
The obvious objection is cost: every layer attending to every earlier layer is quadratic in depth, which for a model this deep is not free. So they block it. Layers are grouped into eight blocks of twelve, and a block representation is computed once at its boundary and shared. Memory and communication drop from growing with the number of layers to growing with the number of blocks. Their earlier work found around eight blocks recovers most of the benefit, which is one of those empirical numbers nobody can justify from first principles and everybody uses anyway.
This introduces gains but are small. Raschka reads it as consistent improvement in validation loss and downstream performance for roughly 4% more training cost and 2% more inference cost. What I think is more interesting about this isn’t the size of the improvement, it’s that it’s the only change here aimed at making the model better rather than cheaper does it by pointing out that a nine-year-old assumption was never examined. I am curious if this will spark ideas to others that will bring further changes in this part of the transformer in future models.
Where K3 actually sits
K3 sits on or near the efficiency frontier across every suite they tested, delivering near-top results at a fraction of the cost of Fable 5. That’s the result of the benchmarks, and it matches how it feels to use. Not “the open models won”, but something more useful: the remaining gap is now narrow enough that it stopped showing up in my work. Benchmarks are a good reference but the real “proof-of-intelligence” is if the model has become your daily driver or not, i.e. if you see yourself resorting to it for everything.
And every change I’ve described points the same way. Cheaper attention, longer context for free, more done per unit of compute. The engineering effort in this release went into efficiency, not capability, and efficiency is what eventually moves a model from a data centre to something a person can own.
The most annoying thing is that you still can’t run this at home realistically. The floor for serving K3 is 8× B300 or 16× B200 GPUs. Open weights, freely licensed, and completely out of reach of anyone reading this on a laptop. I’ve argued before that better maths beats more memory, and I still think that’s right, but the model side is closing that gap considerably faster than the hardware side is.
As a proof of concept, they had K3 design an inference chip for a small model using this same architecture. One 48-hour autonomous run with Kimi Code, open-source EDA tools, 4mm², and it produced a working design clocking over 8,700 tokens per second in simulation. The RTL is on GitHub.
The trend is that new models are trying to squeeze more intelligence per unit of compute and memory, Qwen3.8 and GLM5.3 also introduces interesting improvements in this direction, with GLM5.3 just being a post-training run without any architectural changes, and Qwen3.8 bringing Opus 4.6-level intelligence to your laptop. These are models that you could run at home. But I’ll leave these to next week. See you then!